


ModelDock technical insights
How local AI systems behave under real work.
Short, practical notes on the interactions among model runtime, context, hardware, and agent behavior. These are explanatory frameworks, not substitute benchmark claims.
LatestHardware decisions · 9 min read
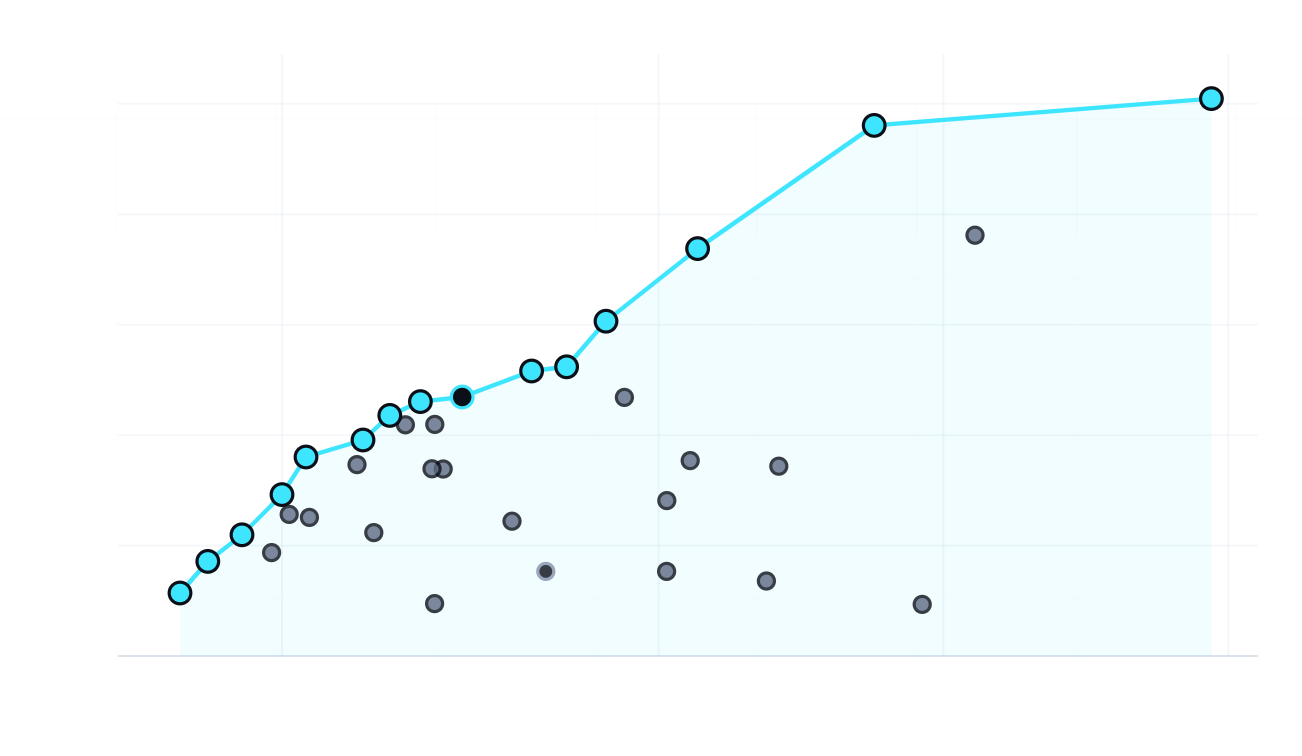
The Price–Performance Frontier of Local AI Hardware
Which machines give the most local AI for their money: a live Pareto frontier of price against daily output, writing and reading speed, and the method behind it.
- 6
- views: three kinds of output by two kinds of cost
- Live
- redrawn from the published data with every release
- 10%
- near-front band: gaps the sources cannot separate
Insight library
All insights
Benchmark data remains on the Benchmark and Data pages. Insights explain what those measurements may mean for a real workload.
The Price–Performance Frontier of Local AI Hardware
Which machines give the most local AI for their money: a live Pareto frontier of price against daily output, writing and reading speed, and the method behind it.
Why Strata Is So Fast on Low-VRAM GPUs
An illustrated overview: the expert cache, CPU and GPU working at once, MTP drafting, PCIe streaming and two-card relays, with measurements against llama.cpp.
Bigger, but Slower: Optimal Context Windows for LLM Agents
A framework for choosing when an agent should compact context, based on observed prefill behavior and reconstruction cost.