


Why Strata Is So Fast on Low-VRAM GPUs
A 125-billion-parameter model on a 12 or 16 GB graphics card, writing four times faster than llama.cpp reading the same file. There is no single trick: Strata treats the whole PC as one pipeline and moves as few bytes as possible through its narrowest pipe.
In short
Strata is an open-source inference engine written for one model family, Qwen3.8-Flash-Next: a mixture-of-experts (MoE) model with 125 billion parameters, of which about 6 billion work on any one token. On a 12 GB RTX 3060 it writes 4.6× faster than a tuned llama.cpp reading the same GGUF file (41.6 against 9.1 tokens per second) and reads a 32K-token prompt 3.1× faster. Four ideas do most of the work:
- Expert by expert, not layer by layer. The model's 24,576 experts are ranked by how often they are used. The graphics card keeps the most-used ones from every layer and keeps learning during the conversation.
- Three workers at once. For every layer, the GPU computes the experts it holds while the CPU computes the missing ones in place in RAM, and a share of the misses is copied over PCIe at the same time.
- Guess, then check. The model's own multi-token-prediction (MTP) layer drafts up to three tokens, and one pass checks them all, so each expensive pass yields two to three tokens.
- Stream in big pieces. Long prompts are read in chunks of thousands of tokens, so every expert copied over PCIe is reused by the whole chunk.
This is the overview. Each part, and the hardware bottlenecks it exposes, will get its own deep dive. Every number below names its source and conditions; the full list is at the end.
The problem: 125 billion parameters, 12 gigabytes
A mixture-of-experts model replaces each dense feed-forward block with many small "experts" and a router that picks a few of them for each token. Qwen3.8-Flash-Next has 48 layers with 512 experts each, 24,576 experts in all, and every layer's router picks 10 per token. A token therefore touches 480 experts: about 2% of them.
That sparsity is what makes a gaming PC plausible. The IQ3_S file Strata recommends for the best quality needs about 50 GB for the experts alone, plus a 29 GB n-gram lookup table and roughly 3.5 GB of weights that every token uses: the attention and DeltaNet mixers, routers, shared experts and the output head. No consumer graphics card holds that. One token, though, needs only the 3.5 GB that is always used and about 1 GB of experts.
Qwen3.8-Flash-Next, IQ3_S · 3.5 + 50 + 29 GB
What one token reads · 3.5 GB + 480 experts ≈ 1 GB
Sizes from Strata’s Models guide (experts in RAM: 50 GB for IQ3_S) and paper Table 1 (always-used weights ≈ 3.5 GB; lookup table 28.8 GB, a few rows read per token). One expert in IQ3_S is about 2 MB; 480 × 2 MB ≈ 1 GB.
So the real question is not how to fit 80 GB into 12. It is which gigabyte the next token will need, where that gigabyte sits right now, and who should compute it. Every design choice below answers that question.
A PC is a set of pipes
A useful picture of Strata is water in pipes. Experts, the KV cache and activations keep flowing between the SSD, RAM, the CPU, the PCIe link and the graphics card's memory. The flow can never be faster than the narrowest pipe on its path, and the pipes in a PC differ by more than an order of magnitude.
Theoretical peak bandwidth from the hardware specifications, log scale; real transfers are lower. The CPU row is measured on ModelDock’s test PC (Ryzen 9 5900XT, 64 GB DDR4-2133): its expert work ran at 22–25 GB/s, the ceiling of that memory.
Two consequences follow. First, a byte should be computed where it already sits. Reading an expert from RAM into the CPU is cheaper than pushing it through a narrow PCIe link to the GPU, so the CPU does real work instead of waiting. Second, the same graphics card can perform very differently in different PCs. Published Strata reports for a single RTX 5070 Ti range from about 50 to 118 tokens per second writing, across host processors, memory and engine versions. On ModelDock's own test PC (PCIe 3.0, DDR4), raising the memory from DDR4-2133 to DDR4-2933 made writing about 20% faster while reading a 150K-token prompt changed by only 3.5%. Which pipe limits which speed is the subject of the first deep dive.
Coarse to fine: four ways to split a model
When a model does not fit in VRAM, a runtime has to decide what stays on the card. The answers have become steadily finer:
- The whole model in VRAM (vLLM, SGLang, or llama.cpp with every layer on the GPU). Fastest when it fits; for this model it means on the order of 100 GB of GPU memory.
- Layer by layer (llama.cpp
-ngl). The first layers run on the GPU and the rest on the CPU, so every token walks through the slow part. - Expert tensors by layer (llama.cpp
--n-cpu-moeor-ot). Attention stays on the GPU and the experts of N layers move to RAM. This is the usual way to run a large MoE model on a small card today. - Expert by expert (Strata). The always-used weights stay on the GPU. The VRAM that is left is filled with individual experts from every layer, chosen by how often they are used, and the CPU computes the rest where they sit.
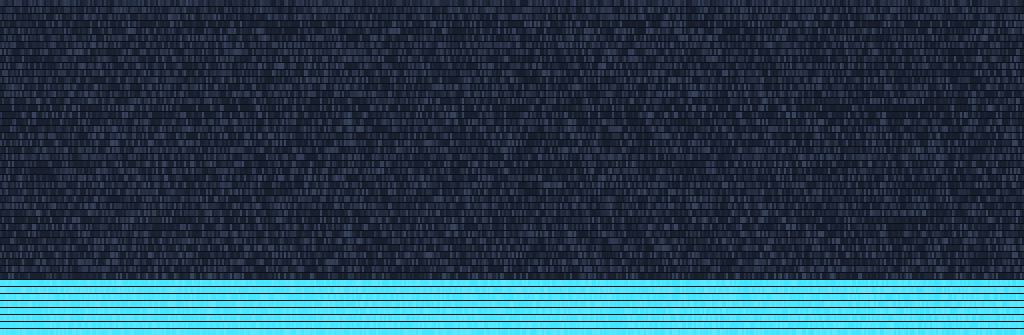
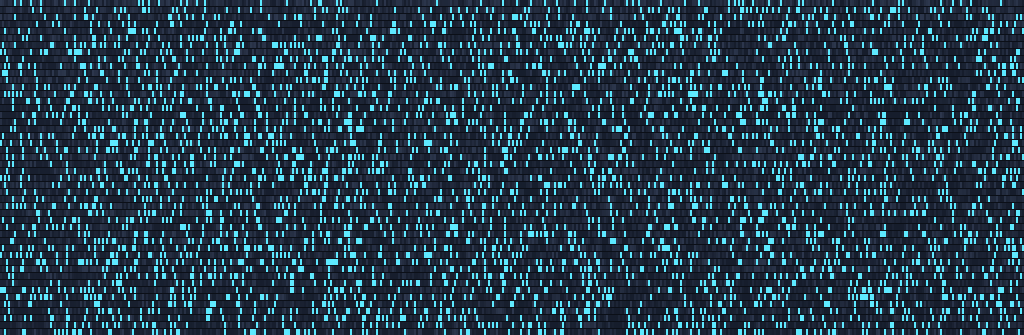
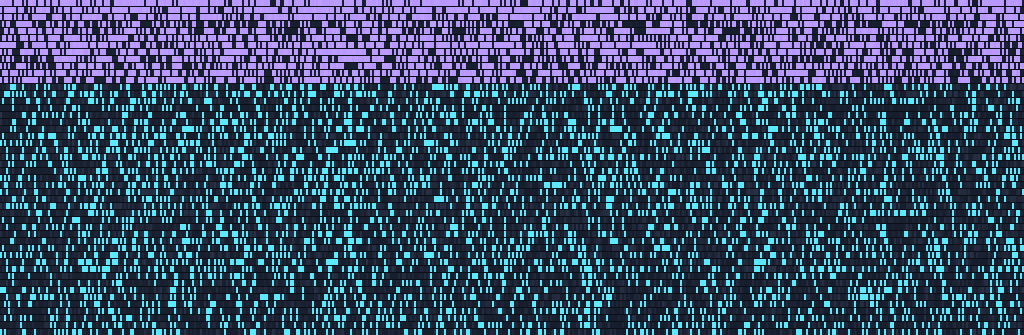
Drawn from Strata’s shipped expert profile, which ranks all 24,576 experts by use; each card fills its slots in that order for its own layers, so the maps approximate the starting placement (the adaptive tier swaps experts during use). The layer-by-layer map is an illustration with the same budget. Slot counts: ModelDock test PC, 3 October 2026.
The maps make the difference visible. With the same budget placed a layer at a time, an expert lookup hits VRAM only when it falls in one of the eight layers the card holds: about one lookup in six. Strata spreads the budget over all 48 layers, between 57 and 109 experts per layer on this card, because the popular experts are scattered. The shipped profile alone serves about half of the routed experts from VRAM on a 12 GB card; the adaptive tier, which swaps up to 96 experts every four rounds toward what the conversation actually uses, raises that to 72% at 4K context. On ModelDock's test PC, the 3,600 to 4,400 experts the RTX 5070 Ti held, 15 to 18% of all experts, served 70 to 78% of expert lookups.
Strata's own rule of thumb follows from this: every extra gigabyte of VRAM holds about 700 more experts, and every expert on the GPU is one the CPU does not compute. More VRAM matters more than a faster GPU.
One token, three workers
Strata's paper calls a decode step "one layer, three workers at once". For every layer, the GPU runs attention and the router and writes the ten chosen expert ids into a small block of pinned host memory, a "doorbell". The CPU, spinning on that doorbell instead of waiting on the driver, splits the work at once: experts already in VRAM go to the GPU, a share of the misses is copied to the GPU over PCIe, and the rest are computed by the CPU cores next to the RAM that holds them. The GPU adds the results and the next layer starts. The whole 48-layer pass is one captured CUDA graph, so the host never waits on a synchronizing driver call.
- GPUattention, router: picks 10 experts
- Doorbell10 expert ids in pinned host memory
-
GPUcomputes the experts already in VRAMPCIecopies a share of the misses to the GPUCPUcomputes the other misses in RAM
- GPUadds the results; next layer
× 48 layers, captured as one CUDA graph
Measured: where a step’s time goes (one RTX 5070 Ti)
Writing speed = tokens kept per step ÷ step time: 1.65 tokens ÷ 35.7 ms ≈ 46 tokens per second.
ModelDock test PC, measured outside the Evidence pipeline: RTX 5070 Ti 16 GB, Ryzen 9 5900XT, 64 GB DDR4-2133, Windows; Strata 0.1.38 with fork patches, IQ3_S, q4_0 KV, MTP, about 3,600 experts in VRAM. A step checks the drafted tokens of one window.
The breakdown shows where the time goes. On ModelDock's test PC the CPU experts take 45 to 52% of each step and run at 22 to 25 GB/s, which is all that DDR4-2133 memory delivers: writing speed on that PC is limited by RAM bandwidth, not by the graphics card. Two things therefore make it faster: fewer misses (more VRAM, a better cache, a second card) and faster RAM. The PCIe share follows the same logic. Up to 0.1.41 it came from the link speed alone (55% of the misses on a fast link); since 0.1.42, on a single NVIDIA card, Strata refines it during the first seconds of writing from the link speed and the CPU's measured speed on missed experts.
Guess, then check
A step that checks several tokens costs only somewhat more than a step that writes one. The always-used weights are read once and the handoffs are paid once; only the experts the extra tokens route add work. So Strata makes each step count. The model ships with its own MTP layer, which drafts up to three next tokens. One pass over all 48 layers checks every draft at once, keeps the ones the full model agrees with, and adds one token of its own.
One pass through all 48 layers checks all three drafts at once
Strata paper, findings 2–3: plain decoding 47–57 tokens per second at 4K, 82–92 with the verify window; greedy speculative output is identical to plain greedy decoding. The sentence is an illustration.
On the paper's reference PC this lifts writing from 47–57 to 82–92 tokens per second at 4K, a 1.6 to 1.8× gain, and the output is identical to plain greedy decoding token for token. The draft layer lives in VRAM and costs 0.8 GB. The comparison with llama.cpp is instructive: its MTP needed a separate 3.4 GB draft head, which pushed more experts to the CPU, and on these cards MTP ended up slower than no MTP at all. On a small card, speculation only helps if it does not cost expert space.
Reading long prompts: stream in big pieces
Reading a prompt (prefill) is a different workload. A prompt of thousands of tokens routes almost every expert of every layer, so caching the popular ones helps little. Strata instead reads long prompts in chunks, up to 8,192 tokens with the automatic setting and larger when configured (ModelDock's test PC uses 16,384), and streams the next layer's experts to the GPU over PCIe while the current layer's attention runs. Every expert copied is then used by the whole chunk, so one transfer is spread over thousands of tokens.
Strata community reports, IQ3_S, prefill (prompt tokens per second). RTX 5070 Ti and RTX 3060 runs with a cold cache; RTX 3060 on 0.1.41, RTX 5090 on 0.1.39. The shaded band marks 8K–16K tokens, where a prompt starts to fill a whole chunk.
The curves explain two things users notice. Short prompts read slowly, because a small chunk still pays for streaming the experts it routes: the RTX 3060 reads a 128-token prompt at about 50 tokens per second and a 32K prompt at 820. Once the chunk is full, reading stays nearly flat to very long contexts, because the sparse attention reads a bounded set of positions: the RTX 5090 in PR #811 still reads 5,535 tokens per second at 261,880 tokens. This is where PCIe matters most. On ModelDock's test PC, a link that had fallen back to PCIe Gen1 cut reading roughly in half until a BIOS setting restored Gen3.
Two cards as a relay
With two graphics cards, Strata splits by layer: pipeline parallelism, not tensor parallelism. The first card runs the first layers; the second runs the rest plus the output head and the draft layer; each caches experts only for its own layers. Activations cross between the cards once per verify window, a few hundred kilobytes through pinned RAM, so neither NVLink nor peer-to-peer support is needed. With pipelined windows, the first card starts the next window on the draft's guess while the last card is still checking the current one, and redoes it if the guess was wrong.
Small card layers 0–11
Big card layers 12–47, output head, draft
CPU experts neither card holds
HandoffThe next card waits on a flag in pinned memory: a few hundred KB per window, no NVLink or peer-to-peer.
PipeliningWhile the big card checks window K, the small card starts K+1 on the draft’s guess and redoes it if the guess was wrong.
CPU shareThe CPU computes the experts no card holds, in parallel with both cards.
Long promptsExperts stream over PCIe one chunk at a time (15,360 tokens on the test PC); with only one or two chunks the two stages run one after the other.
Schematic, not to scale. Layer split and pipelined windows: Strata Multi-GPU guide; the flag handoff comes from the Hardin22/Strata-DualGPU fork.
On ModelDock's test PC the gain came mostly from capacity, not from the pipeline itself. The two cards held 8,412 experts instead of 4,176, the CPU computed 59% fewer experts per layer and step, and a step shrank from 36.7 to 23.8 ms; pipelining alone was worth about 4 to 6%. Reading did not get faster. With only one or two chunks the two stages still run one after the other, so 8K to 64K prompts read 18 to 53% slower, and only at 150K did two cards match one.
Writing, short chat tok/s
+54%Writing at 150K context tok/s
+37%Reading a 150K prompt tok/s
≈Experts in VRAM
×2Experts the CPU computes per layer and step
−59%Time per step, short chat ms
−35%But mid-length prompts read slower on two cards (tok/s, one → two)
ModelDock test PC, 3 October 2026, measured outside the Evidence pipeline. One card: RTX 5070 Ti 16 GB, mapped experts. Two cards: RTX 3060 12 GB (layers 0–11) + RTX 5070 Ti (12–47, head, draft), PCIe 3.0 x8 each, resident experts, pipelined windows. Ryzen 9 5900XT, 64 GB DDR4-2133, Windows; IQ3_S, q4_0 KV, MTP, greedy; Strata 0.1.38 + Hardin22/Strata-DualGPU (#642) in the architectds/Strata fork. With mapped experts on both arms, two cards measured 68.3 / 59.7 / 1,609.
Published reports point the same way. On one host with two RX 6900 XT cards (Strata 0.1.40.1, PR #1270), the split raised writing by 32% and reading by 66% over one card, while a 4K prompt read 3% slower. A split pays where the extra VRAM removes CPU work; it does not make either card faster.
Measured: Strata against llama.cpp
The fairest comparison available is Strata's own head-to-head of 6 October 2026: the same IQ3_XXS GGUF file read by both engines, llama.cpp v0.6.0 tuned with -ncmoe and -ub sweeps, and the same prompts. Strata led every measured row.
RTX 3060 12 GB · writing, 4K prompt tok/s
4.6×RTX 3060 12 GB · reading a 32K prompt tok/s
3.1×Tesla P100 16 GB · writing, 32K prompt tok/s
3.6×Tesla P100 16 GB · reading a 32K prompt tok/s
2.1×RTX 5070 12 GB · reading a 32K prompt tok/s · one round
8.8×Strata’s head-to-head of 6 October 2026: Qwen3.8-Flash-Next GSQ-RCO IQ3_XXS read by both engines; llama.cpp v0.6.0 (b11429) tuned with -ncmoe and -ub sweeps (RTX 5070: --fit on); medians of 256-token answers at temperature 0; Strata with its setup config (MTP, int8 KV). RTX 3060: 46 GB RAM, Linux; Tesla P100: 62 GB, Linux; RTX 5070: 64 GB, Windows.
The report states its limits: few rounds, a small tuning sweep, no per-tensor -ot patterns, and an MTP head for llama.cpp that is not the model's native one. Its authors expect a heavier llama.cpp tune to add some percent, not to close a 4× gap. A comparison on a different class of machine points the same way: on an AMD Ryzen AI Max+ 395 with 128 GB of unified memory, Strata 0.1.40 wrote at about 51 tokens per second at 128K (UD-IQ4_XS, MTP) against about 15.5 for llama.cpp's Vulkan build with the larger UD-Q4_K_XL file and no draft model. The quantization and setup differ, so read that as a direction, not a ratio.
Strata is not the fastest everywhere. When the whole model fits in GPU memory, a server engine wins: an RTX PRO 6000 with 96 GB on SGLang (NVFP4) writes 171 tokens per second and reads over 10,000 at 64K, against 168 and 5,803 for the RTX 5090 on Strata. Strata answers "the model does not fit"; it does not replace an all-in-VRAM server.
What it costs
- One model family. Strata is built for Qwen3.8-Flash-Next and its fine-tunes. It is not a general runtime.
- Short prompts and the first message. A 512-token prompt reads at a fraction of the long-prompt speed, and a fresh 30K-token conversation takes about a minute to read on a 12 GB card. Follow-ups reuse the conversation and read only what is new.
- RAM still matters. The experts live in RAM: about 50 GB for IQ3_S and 34 GB for Q2_0, plus about 10 GB for the system. A low-RAM mode exists for big cards with little RAM.
- Smaller MTP gains. 1.6 to 1.8× instead of the 2.5 to 3× engines report with the whole model in VRAM, because every extra drafted token routes to its own CPU experts.
- Not bit-identical across settings. Greedy speculation matches greedy decoding, but CPU and GPU kernels round differently, and the adaptive cache, CPU share and tail skip change the last bits, so two configurations can diverge after a while.
- One request at a time by default. Parallel slots on a 12 GB card are slower.
Frequently asked questions
Can Strata run on an 8 GB graphics card?
Strata targets NVIDIA and AMD cards with 12 GB or more. Below that, too little VRAM is left for the expert cache once the always-used weights, the KV cache and the draft layer are in place.
How much RAM does Strata need?
All experts live in RAM: about 34 GB for Q2_0, 35.5 GB for IQ2_XS, 43 GB for IQ3_XXS and 50 GB for IQ3_S, plus about 10 GB for Windows and other programs. With 64 GB every size fits; with 48 GB, Q2_0 and IQ2_XS.
Is Strata faster than llama.cpp, Ollama or LM Studio?
On the same GGUF file and 12 to 16 GB cards, Strata's published head-to-head measured 3.0 to 4.7× faster writing and 1.6 to 8.8× faster reading than llama.cpp. ModelDock has no published Ollama or LM Studio measurement of this model on these cards.
Do two GPUs need NVLink or matching models?
No. The layer split passes a few hundred kilobytes per window through pinned system memory, so mixed cards work without NVLink or peer-to-peer; ModelDock's test PC pairs an RTX 3060 with an RTX 5070 Ti. The faster card goes last, because it runs the output head and the draft layer.
Should I buy more VRAM or a faster GPU?
For this model, more VRAM usually wins: each extra gigabyte holds about 700 more experts, and each of them is one the CPU no longer computes. The memory and PCIe of the PC around the card matter as well, which is the subject of the first deep dive.
How can I measure my own PC?
Use the ModelDock Speed Test: paste one line to your AI agent, and it runs a standard local benchmark and returns a share card. Compare machines in the Rankings and the Benchmark workbench.
What comes next
This overview is the map. Each deep dive will take one part further:
- Bottlenecks by machine. Memory bandwidth, PCIe generation and lanes, DDR4 against DDR5: why the same RTX 5070 Ti can be twice as fast in another PC, and when an older platform needs one large-VRAM card while a newer one can use two smaller cards.
- The expert cache. Profiles, adaptive swaps, and why the hit rate falls over a long session.
- Guess, then check. MTP drafting when most of the model lives in RAM.
- Two cards as a relay. Split points, pipelined windows and the handoff through pinned memory.
- Long prompts. Chunk sizes, PCIe streaming and the CPU share for short prompts.
Sources and conditions
- Strata (MIT), release 0.1.42 of 10 October 2026: How it works, Models, Multi-GPU and the paper Running a 125-Billion-Parameter Model on a Normal PC (September 2026; reference PC: RTX 5070 12 GB, 64 GB DDR5, six cores).
- Strata against llama.cpp v0.6.0, 6 October 2026: IQ3_XXS GGUF; RTX 3060 12 GB with 46 GB RAM (Linux), Tesla P100 16 GB with 62 GB (Linux), RTX 5070 12 GB with 64 GB (Windows, one round, llama.cpp
--fit on); medians of 256-token answers. - Expert maps: drawn from Strata's shipped expert profile, which ranks all 24,576 experts; a card fills its slots in that order for its own layers. The maps approximate the starting placement; the adaptive tier changes it during use.
- ModelDock test PC, 3 October 2026, measured outside the ModelDock Evidence pipeline: RTX 5070 Ti 16 GB and RTX 3060 12 GB (PCIe 3.0, x8 each with two cards), Ryzen 9 5900XT, 64 GB DDR4-2133, Windows; Qwen3.8-Flash-Next GSQ-RCO IQ3_S, q4_0 KV, MTP, greedy; Strata 0.1.38 with the Hardin22/Strata-DualGPU patches (#642) in the architectds/Strata fork. "Short" is three chat prompts with 400-token answers; "150K" is a cold 150,228-token code prompt.
- Reading curves: RTX 5070 Ti with Core Ultra 7 265K (issue #791, IQ3_S, cold cache); RTX 3060 12 GB with Core i7-12700 (PR #1725, 0.1.41, IQ3_S, cold cache); RTX 5090 with Ryzen 7 9700X (PR #811, 0.1.39, IQ3_S).
- Two RX 6900 XT on one host, Strata 0.1.40.1, IQ3_S, 131K context (PR #1270).
- Ryzen AI Max+ 395: Strata v0.1.40 release notes; llama.cpp b10707 Vulkan (soothill.io, 27 August 2026).
- All-in-VRAM reference: RTX PRO 6000 96 GB on SGLang, NVFP4 (results).
- RTX 5070 Ti host spread and the other hardware records: ModelDock Data and Evidence.